Chengxuan Li 'Charles'
Robotics Researcher
The Chinese University of Hong Kong (CUHK)
MPhil in Electronic Engineering
cxli2004(at)outlook.com
About Me

I am an MPhil student at The Chinese University of Hong Kong (CUHK), advised by Prof. Hongliang Ren at the Robotics, Embodied AI, Navigation in Vivo Lab (RENLab). My research interests lie in Embodied AI, Robotics, and World Model. Learn more about my research here.

Research keywords include: Embodied AI, Robotic Manipulation, and so on.

Brief Biography

I am currently a MPhil student at CUHK. Previously, I received my B.Eng. in Automation from Beijing Forestry University in 2026. I have also conducted research at Peking University and the Institute of Automation, Chinese Academy of Sciences (CASIA).

News
2026
Joined RENLab @ CUHK as a MPhil student.
Aug 01
Received my B.Eng. from Beijing Forestry University.
Jun 10
One paper on World Model accepted in ICML 2026.
May 01
Attending AAAI 2026 at Singapore and giving an oral talk.
Jan 23
2025
Two papers on VLA accepted in AAAI 2026.
Nov 08
Research Highlights
* Equal contribution, † Corresponding author
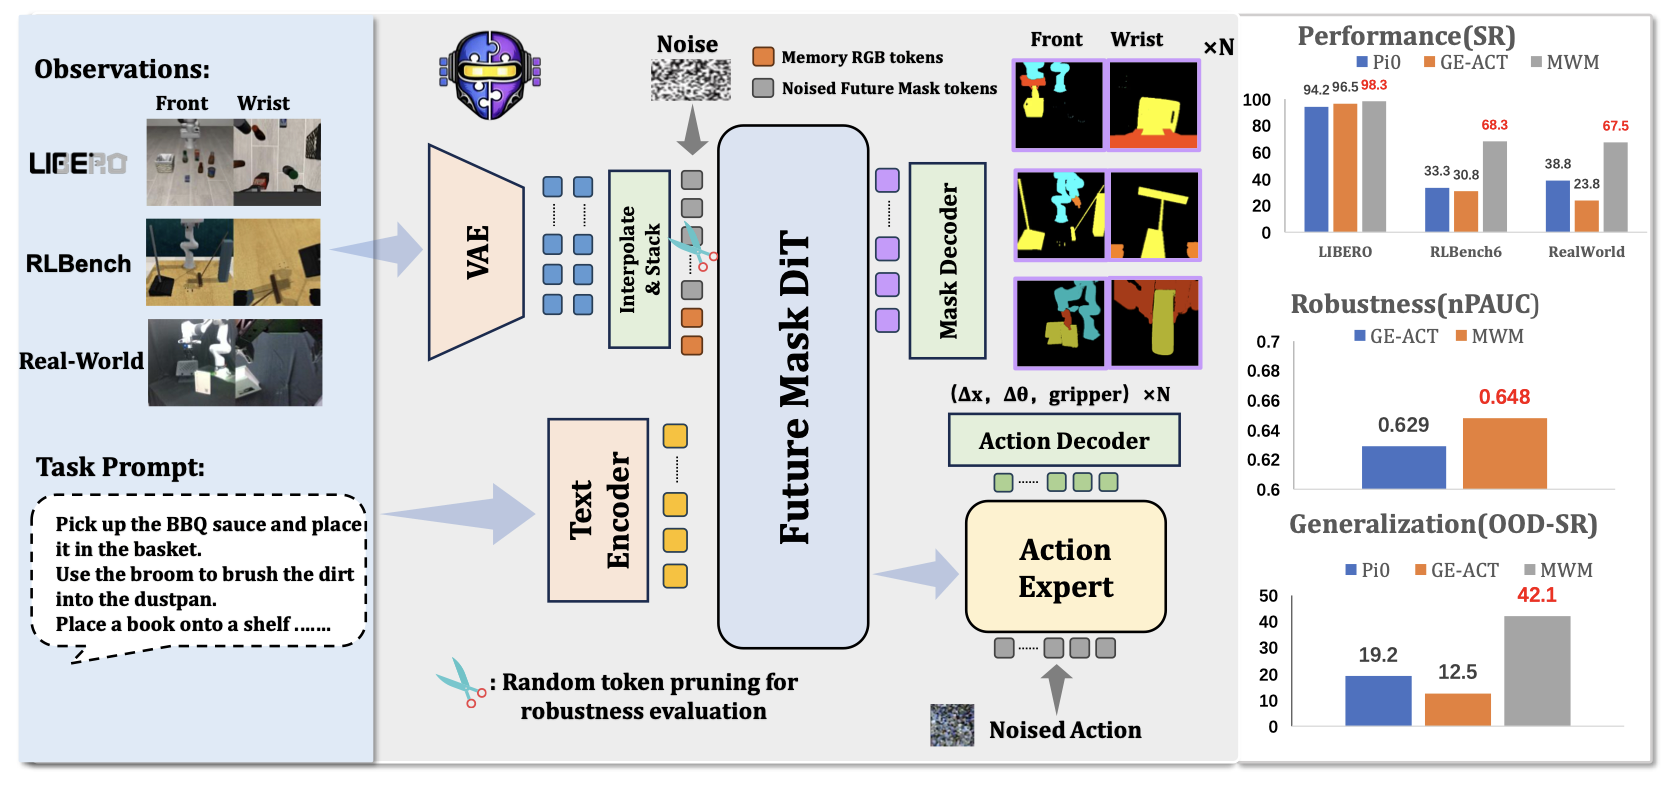
Mask World Model: Predicting What Matters for Robust Robot Policy Learning

Yunfan Lou*, Xiaowei Chi*, Xiaojie Zhang*, Zezhong Qian, Chengxuan Li, Rongyu Zhang, Yaoxu Lyu, Guoyu Song, Chuyao Fu, Haoxuan Xu, Pengwei Wang, Shanghang Zhang†

ICML 2026 poster

# world-model

Mask World Model: Predicting What Matters for Robust Robot Policy Learning

Yunfan Lou*, Xiaowei Chi*, Xiaojie Zhang*, Zezhong Qian, Chengxuan Li, Rongyu Zhang, Yaoxu Lyu, Guoyu Song, Chuyao Fu, Haoxuan Xu, Pengwei Wang, Shanghang Zhang†

ICML 2026 poster

# world-model

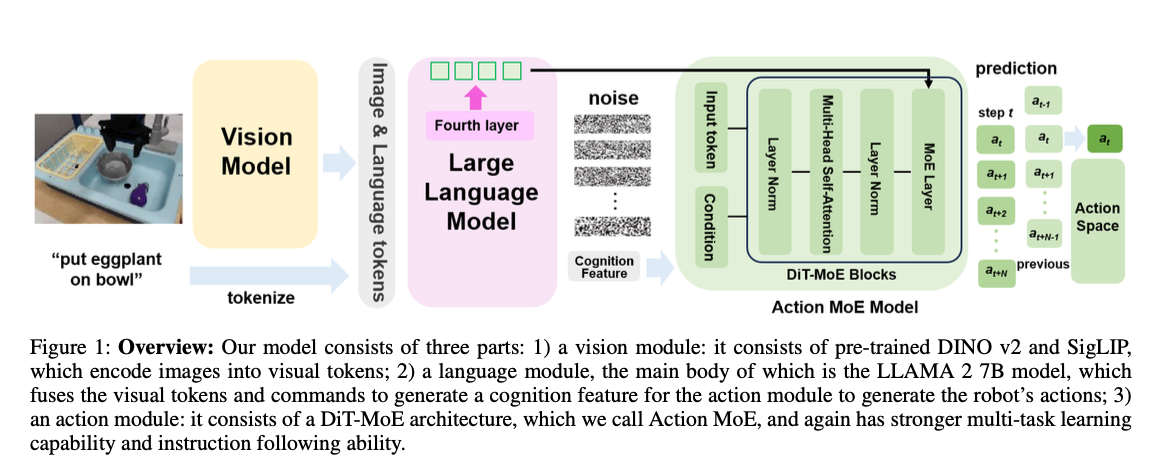
DiTEA: Mixture-of-Experts for Vision-Language-Action Model in Robotic Manipulation

Chengxuan Li*†, Xingwan Wang*

AAAI 2026 oral

# vla

DiTEA: Mixture-of-Experts for Vision-Language-Action Model in Robotic Manipulation

Chengxuan Li*†, Xingwan Wang*

AAAI 2026 oral

# vla

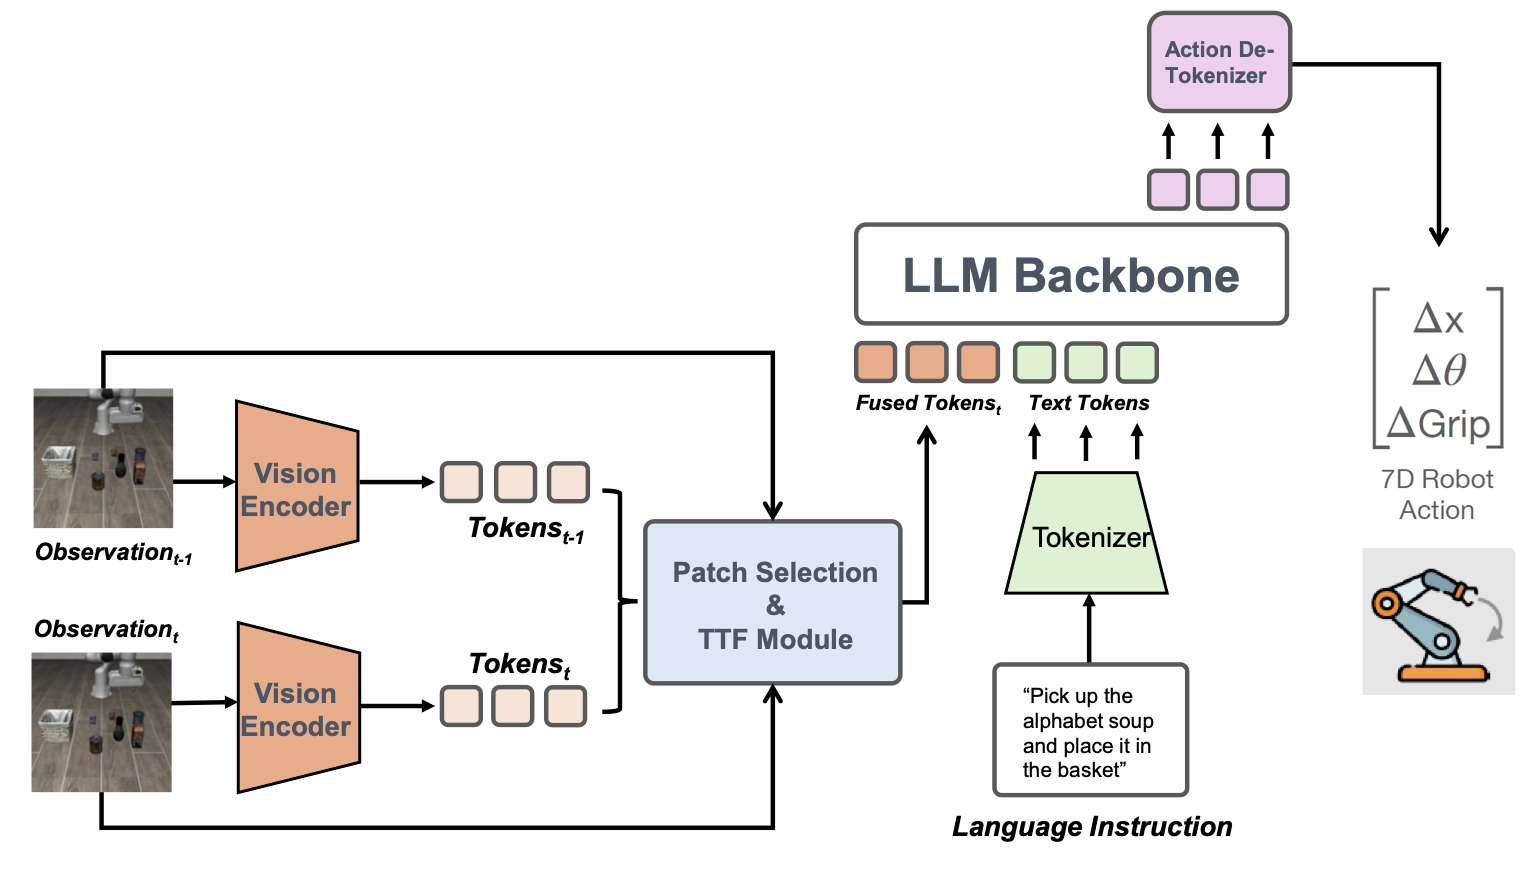
TTF-VLA: Temporal Token Fusion via Pixel-Attention Integration for Vision-Language-Action Models

Chenghao Liu*, Jiachen Zhang*, Chengxuan Li*, Zhimu Zhou, Shixin Wu, Songfang Huang†, Huiling Duan†

AAAI 2026 poster

# vla

TTF-VLA: Temporal Token Fusion via Pixel-Attention Integration for Vision-Language-Action Models

Chenghao Liu*, Jiachen Zhang*, Chengxuan Li*, Zhimu Zhou, Shixin Wu, Songfang Huang†, Huiling Duan†

AAAI 2026 poster

# vla

All Research